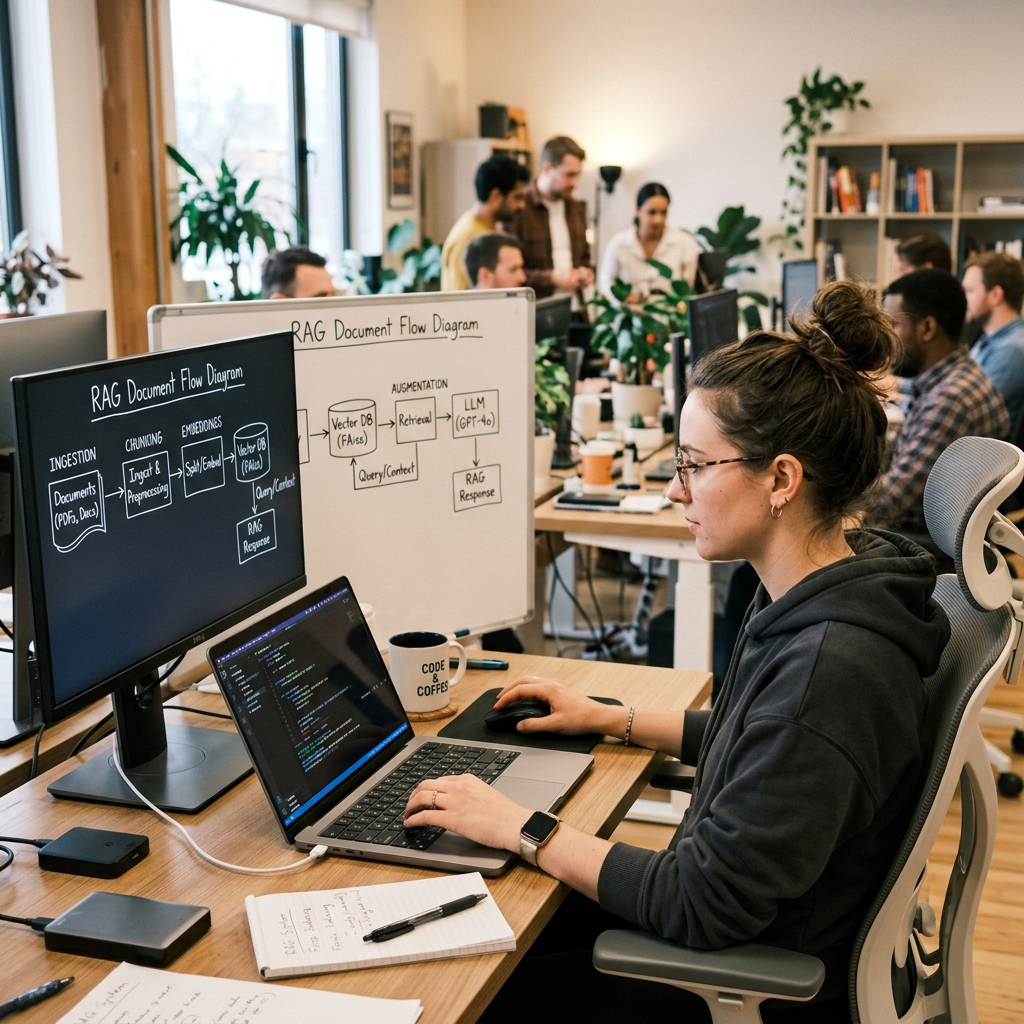
Our support team kept asking me the same thing: “Can we just get a bot that actually knows our product?” The LLM we were using sounded confident, but it did not know our data. It would answer beautifully and still be wrong. It missed our latest policy updates, got internal product names confused, and ignored the one document that actually mattered.
So I built a Q&A system over our internal docs. The architecture behind it is called Retrieval-Augmented Generation, or RAG, and it turned out to be the most practical thing I have shipped with an LLM.
The idea is straightforward. Instead of asking the model to rely only on what it learned during training, you give it access to relevant information at query time. You fetch the right context first, then let the model write the answer.
Related: If you want the bigger picture first, read my simple guide to LLMs and how large language models actually work. For the customization angle, see Choosing Between Fine-Tuning, LoRA, and RAG.
Try it yourself: All the RAG vs plain LLM comparisons in this post were generated by running a demo script that chunks 6 company documents, builds a TF-IDF index, retrieves relevant context, and compares grounded vs ungrounded answers from
gpt-4o-mini. You can install it withpip install requests rich numpy scikit-learnand run it to test RAG against your own documents.
What RAG Actually Is
RAG stands for Retrieval-Augmented Generation. The name is long, but each piece is simple:
- Retrieval means finding relevant information from a source you control.
- Augmented means adding that information to the prompt or context.
- Generation means letting the LLM produce the final answer.
Instead of prompting the model with only a user question, you first retrieve supporting documents, snippets, or records. Then you send those into the model so it can answer with the right context.
I think of it as giving a smart researcher access to a filing cabinet before they write a response. The model still does the writing, but it is no longer working blind.
Why I Chose RAG Over Other Approaches
I had several reasons for building RAG instead of fine-tuning or just writing better prompts.
It reduces hallucinations
LLMs are good at generating fluent text, but fluency is not accuracy. When the answer depends on a company policy or a product manual, the model needs help. RAG grounds the response in source material. Once I had retrieval working, the hallucination rate on product questions dropped noticeably.
It keeps knowledge up to date
Our docs change weekly. Fine-tuning is not the easiest way to keep up with that cadence. With RAG, I update the index when content changes. No retraining required.
It makes answers easier to trust
When the bot shows the source passage behind an answer, our support team can verify it in seconds. That trust factor was a bigger deal than I expected. People stopped treating the bot as unreliable and started using it as a first step.
It is cheaper and faster to maintain
No model retraining every time content changes. Update the index, tune retrieval, improve the pipeline. The ongoing cost is manageable.
How the System Works
The RAG system I built has four parts:
- Source data — our internal docs, FAQs, product guides, and support tickets.
- Indexing pipeline — the content gets cleaned, split into chunks, and converted into embeddings using an embedding model. Those embeddings go into a vector database with metadata attached.
- Retrieval layer — when a user asks a question, the query gets embedded too. The system searches the vector database for the most relevant chunks.
- Generation layer — the retrieved chunks are added to the prompt, and the LLM produces the final answer.
The flow in simple form:
User Question -> Retrieve Relevant Context -> Send Context to LLM -> Generate Answer
That is the core pattern. Everything else is refinement.
RAG vs Plain LLM: Real Output Comparison
To prove the difference, I ran 5 questions against the same gpt-4o-mini model — once with no context (plain LLM) and once with retrieved document chunks (RAG). The RAG pipeline indexed 6 internal company documents, split them into 14 chunks, and retrieved the top 3 most relevant chunks per question.
The results speak for themselves.
“Does CodeBuddy support Kotlin?”
Plain LLM: “Yes, CodeBuddy supports Kotlin. You can use it for various tasks such as coding assistance, debugging, and learning Kotlin programming.”
RAG: “No, CodeBuddy does not support Kotlin as of version 2.4. [Source: products/codebuddy.md]”
The plain LLM confidently hallucinated “Yes.” The actual document says CodeBuddy does NOT support Kotlin. RAG retrieved the right chunk and got the correct answer. This is the hallucination problem in one example.
“What is the return policy for software licenses?”
Plain LLM: A generic 5-paragraph essay about how “return policies can vary depending on the company” with no specific information.
RAG: “Software licenses are non-refundable after activation. [Source: policies/returns.md | Return Policy]”
One sentence, correct, with a source citation. The plain LLM had no choice but to hedge because it does not know our policy.
“What’s the emergency support phone number?”
Plain LLM: “Please contact ByteMind AI’s customer support directly through the official website or the support portal.”
RAG: “The emergency support phone number is +31-20-555-0199. [Source: support/hours.md | Technical Support Hours]”
The plain LLM could not give the number because it was never in its training data. RAG found it in the support hours document.
Full Results Table
| Question | Plain LLM | RAG | Verdict |
|---|---|---|---|
| Return policy for software? | Generic essay, no specifics | “Non-refundable after activation” + source | RAG grounded |
| Does CodeBuddy support Kotlin? | “Yes” (wrong) | “No, not as of v2.4” + source | RAG prevented hallucination |
| Where does ByteMind ship from? | “Various regions” (vague) | “Rotterdam, Netherlands” + source | RAG specific |
| Emergency phone number? | “Contact the website” (useless) | “+31-20-555-0199” + source | RAG factual |
| Is my code used for training? | Correct guess, no evidence | Correct + “deleted within 30 seconds” + source | RAG cited |
The same model powers both columns. The only difference is whether it gets retrieved context. That difference turned a hallucinating chatbot into a reliable support agent.
What Makes a Good RAG System
A lot of people think RAG is just “vector search plus an LLM.” That is the starting point, not the finish line. The quality of your system depends on several details that are easy to get wrong.
Chunking
If your documents are split poorly, retrieval suffers. Chunks that are too large bury the relevant sentence. Chunks that are too small lose context. I spent more time on chunking than I expected, and it was worth it.
Embeddings
Embeddings determine how well the system understands similarity. Good embeddings find related content even when the wording is different. The choice of embedding model matters more than most tutorials suggest.
Retrieval strategy
Vector search is useful but not always enough by itself. Many real systems use hybrid retrieval (combining semantic and keyword search), metadata filters, or reranking to improve results.
Prompt assembly
The retrieved text has to be packaged well for the model. If the prompt is messy or the context is poorly formatted, answer quality drops even when retrieval is good.
Guardrails
You still need to control the output. A retrieved passage should guide the model, not completely override good response design.
For more on how these techniques relate to fine-tuning, Choosing Between Fine-Tuning, LoRA, and RAG is a good companion read.
When to Use RAG Instead of Fine-Tuning
This came up repeatedly when I was deciding how to build our system.
Use RAG when:
- your content changes often,
- your answers must reflect current documents,
- you need source-backed responses,
- your use case depends on private or internal knowledge.
Use fine-tuning when:
- you want a consistent output style,
- you need the model to follow a very specific behavior pattern,
- your task depends more on format or judgment than on fresh knowledge.
In practice, many teams use both. RAG handles knowledge. Fine-tuning handles behavior. I ended up adding a LoRA adapter for tone on top of our RAG pipeline.
Practical Design Choices That Mattered
Here are the decisions that had the most impact when I was building our system.
1. Choose the right data source
I started with content that was trusted and stable enough to index. Messy source data produces messy retrieval. We cleaned up our docs before indexing them, which felt tedious but paid off immediately.
2. Keep chunk boundaries sensible
Preserving meaning beats preserving length. A heading, paragraph, or small section works better than splitting on arbitrary character counts. I ended up chunking by section header for most of our docs.
3. Store metadata
Document title, section name, product version, date, and source URL all improve filtering and citations. Metadata turned out to be just as important as the embeddings for our use case.
4. Add citations when possible
Even a simple “Source: API Guide, Section 4” makes the system dramatically more usable. Our support team told me citations were the feature that made them trust the bot.
5. Measure retrieval quality separately
Do not wait until the final answer to discover retrieval is weak. I built a small test set of questions and checked whether the right chunks were being found before worrying about generation quality.
For a broader implementation walkthrough, see Building an LLM App: A Practical Guide From Prototype to Production.
What Didn’t Work / Common Mistakes I Made
RAG is powerful, but it is easy to get wrong in predictable ways.
- Too much text in one chunk: retrieval becomes fuzzy because the relevant sentence is buried.
- Too little text in one chunk: the model loses context and the answer feels fragmented.
- No reranking: the top search results are not always the best results. I added reranking after seeing too many cases where the second or third result was actually the right one.
- No evaluation set: guessing instead of measuring. Building even a small eval set changed how I made decisions.
- Treating the model as the source of truth: the retrieved documents should lead the answer, not the model’s training data.
These mistakes are not exotic. They are ordinary engineering problems, which is good news because ordinary engineering problems can be fixed.
If you are also working on prompt quality, it is worth revisiting Prompt Engineering Practical Techniques.
A Basic RAG Architecture You Can Actually Build
A useful first version does not need to be complicated. Here is roughly what I built for version one.
Ingestion
- Pull content from docs, PDFs, or a knowledge base.
- Clean up formatting.
- Split into chunks.
- Create embeddings.
- Store them in a vector database with metadata.
Query time
- Receive the user question.
- Embed the query.
- Retrieve the most relevant chunks.
- Optionally rerank the results.
- Build a prompt with the question and context.
- Generate the answer.
Response handling
- Show the answer.
- Include citations or source links.
- Log the query, retrieved chunks, and output for evaluation.
That architecture is simple enough for a first prototype and sturdy enough to improve later.
External Reading Worth Bookmarking
Further Reading:
These are useful if you want to compare implementation approaches and see how different teams frame the same problem.
Final Thoughts: The Pipeline Matters More Than the Model
The thing I did not expect when building our RAG system was how much the non-model parts mattered. I spent maybe 20% of my time on the LLM prompt and 80% on chunking, retrieval tuning, metadata, and evaluation. The model was the easy part. The pipeline around it determined whether answers were actually good.
If your product depends on changing documents, internal knowledge, or support content, RAG is usually the first architecture worth getting right. The biggest wins come from the basics: good chunking, solid retrieval, useful citations, and regular evaluation.
Start by making retrieval reliable. Everything else builds on that.
Previously: I Needed My LLM to Sound Like Us: Choosing Between Fine-Tuning, LoRA, and RAG. Next: My RAG App Gave Wrong Answers: How I Fixed It.
Leave a Reply